“既然数据能自己取,就没必要把它交给一台要花钱的服务器。”
最近在运营单位的公众号,看到别人文章里那种数据看板——顶部一排 KPI、阅读分享趋势、粉丝增长、来源构成、文章榜单和明细表——我就想搞清楚一件事:这个”自动同步公众号阅读数据”的看板,到底是怎么实现的? 而我的要求很朴素:本地跑、页面尽量简单、不要数据库、不要云服务,最好一分钱都不花。
这篇文章把整个项目的来龙去脉、全部完整源码、零基础使用教程、踩坑和后续维护都记录下来。哪怕你完全不会编程,照着一步步复制粘贴,也能在自己电脑上跑起来。
说明:本文面向 Windows / macOS / Linux(含统信 UOS 等国产系统),代码以 Linux 路径为主,Windows/Mac 的差异会在对应位置单独说明。
目录
- 项目初衷与背景
- 先搞懂几个名词(小白必看)
- 三条”能白嫖”的路,为什么全走不通
- 最终方案:本地 Python + JSON + 单文件 HTML
- 你需要准备什么,以及如何获取 AppID / AppSecret
- 完整源码(5 个文件,直接复制)
- 从零开始:手把手搭建与运行
- 设置每天自动同步
- 看板功能说明(含合集的限制)
- 常见问题与错误码速查
- 后续维护与备份
一、项目初衷与背景
我最初想要的,是一个会自动更新的公众号数据看板:
- 每天自动把昨天的阅读、分享、收藏、点赞、在看、留言、粉丝数据拉下来;
- 用图表展示趋势、来源构成、文章榜单;
- 用明细表列出每篇文章,并支持筛选、排序、导出 Excel。
但我有几个”小气”的要求:不花钱、不买服务器、不搭数据库、不依赖云服务。于是我先把微信官方的规则和各种”白嫖”方案都摸了一遍,才确定最终做法。
二、先搞懂几个名词(小白必看)
在动手之前,先把这几个词搞明白,后面的步骤就不会懵:
| 名词 | 通俗解释 |
|---|---|
| AppID(开发者ID) | 公众号的”身份证号”,以 wx 开头,公开可查,不保密。 |
| AppSecret(开发者密码) | 公众号的”密码”,非常重要、不能泄露,用来换取 access_token。 |
| access_token(访问令牌) | 一个”临时通行证”,脚本拿 AppID+AppSecret 换来,之后所有数据请求都要带它。有效期 7200 秒(2 小时),过期要重新换。 |
| IP 白名单 | 微信只允许”白名单里的电脑 IP”去取数据。你必须把自己电脑的公网 IP 填进后台,否则一律拒绝。 |
| 公网 IP | 你家宽带在互联网上的”门牌号”。可在 https://ip.cn 查到,脚本首次运行时也会提示。 |
| datacube(数据统计接口) | 微信官方提供的一组数据接口,用来取阅读、分享、粉丝等数据。 |
| UV / PV | UV=阅读人数(同一个人看多次只算 1);PV=阅读次数。微信自 2025-11-01 起只保留 UV,取消了 PV。 |
还有一个最重要的前提:
数据统计接口只对”已认证的订阅号 / 服务号”开放。 未认证的订阅号、个人号,是调不了这些数据接口的。请先确认你的公众号已经通过微信认证。
三、三条”能白嫖”的路,为什么全走不通
我一开始并不想写脚本,于是先把几条偷懒的路子都试了一遍。
1. 纯静态 HTML 直接调微信接口?不行
- CORS:浏览器跨域被拦,微信接口不允许网页直接请求;
- AppSecret 泄露:前端页面里写死密码,等于把密码公之于众;
- IP 白名单:页面跑在每个访客自己的网络里,IP 不固定,没法加白名单。
2. 用 Cloudflare Workers 免费版?不行
免费版的出口 IP 是动态共享地址,每天在变,无法加白名单;想要固定出口 IP 就必须用付费方案。
3. 用 GitHub Actions 代跑?也不行
GitHub Actions 的出口 IP 同样是一大段动态地址段,无法固定加白名单。
结论
能同时满足”服务端调用 + IP 白名单 + token 中控“又不花钱的办法,只剩一个:在自己电脑上跑脚本采集。 这就是本文的「方案 A」。
四、最终方案:本地 Python + JSON + 单文件 HTML
整体架构非常简单,没有任何一台云服务器:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
  ┌────────────┐   每天定时(8:30)   ┌──────────────────────┐
  │  定时任务    │ ───────────────▶ │      sync.py         │
  └────────────┘                   │  (token 中控 + 采集)  │
                                   └──────────┬───────────┘
                                              │ 写入
                                    ┌─────────▼─────────┐
                                    │  store.json (数据库) │
                                    └─────────┬─────────┘
                                              │ 生成
                                    ┌─────────▼─────────┐
                                    │      data.js       │
                                    └─────────┬─────────┘
                                              │ 读取
                                    ┌─────────▼─────────┐
                                    │    index.html 看板  │
                                    └───────────────────┘
关键思想:
- 采集:
sync.py用 access_token 调微信接口,把数据累加合并进store.json; - 存储:不装数据库,一个 JSON 文件就是数据库;
- 展示:
index.html读取sync.py生成的data.js(用<script>标签加载,规避file://下不能 fetch 本地文件的问题); - 零依赖:Python 端只用标准库,不需要 pip 安装任何东西。
项目文件清单(共 5 个需要你创建的文件):
| 文件 | 作用 |
|---|---|
config.json |
配置:AppID / AppSecret / 回溯天数(需要你填) |
sync.py |
采集脚本,核心 |
run.sh |
一键运行入口(Linux/Mac) |
index.html |
数据看板,双击打开 |
README.md |
部署说明(可留可不留) |
运行后会自动生成:
| 文件 | 作用 |
|---|---|
token.json |
缓存 access_token(含过期时间) |
store.json |
累积的全部历史数据,也就是”数据库” |
data.js |
看板读取的数据 |
sync.log |
定时任务日志 |
五、你需要准备什么,以及如何获取 AppID / AppSecret
1. 你需要准备的 4 样东西
| 信息 | 在哪里获取 | 说明 |
|---|---|---|
| AppID | 微信公众平台 → 设置与开发 → 基本配置 | 以 wx 开头 |
| AppSecret | 同上 → 开发者密码(点「重置」可见,需管理员扫码) | 只填到本机,不要发给任何人 |
| 本机出口公网 IP | 浏览器打开 https://ip.cn 查看,或首跑脚本时提示 | 要加进白名单 |
| 公众号状态 | —— | 必须是已认证的订阅号 / 服务号 |
2. 手把手获取 AppID / AppSecret(跟着点)
- 电脑浏览器打开微信公众平台:https://mp.weixin.qq.com
- 用绑定该公众号的管理员微信扫码登录(手机上确认)。
- 登录后,把左侧菜单栏拉到最下方,找到 「设置与开发」→ 点开 → 点「基本配置」。
- 在页面中部的 「开发者ID」 区域:
- AppID(开发者ID):直接显示,一串
wx开头的字符,点旁边的「复制」。 - AppSecret(开发者密码):默认是隐藏的,点右边的 「重置」(有的显示「生成」)。
- 会弹出一个二维码,用管理员微信扫码确认;
- 确认后页面显示一串密码,立刻复制并保存好(它只完整显示这一次,关掉窗口后就只能再次「重置」)。
- AppID(开发者ID):直接显示,一串
- 还是在这个页面,往下找到 「IP白名单」,点「修改」:
- 把你的公网 IP(https://ip.cn 查到的那个)填进去;
- 支持单个 IP:
1.2.3.4; - 支持 IP 段:
1.2.3.4/24(不支持1.2.3.*这种写法); - 家庭宽带 IP 偶尔会变,变了脚本会再次提示,照提示更新即可。
安全提醒:AppSecret 只填在你自己电脑的
config.json里,不要发给任何人、不要贴到聊天群、不要写进任何网页。
3. 确认电脑装了 Python
- Linux / 统信 UOS:一般自带。在文件夹空白处右键「在终端打开」,输入
python3 --version,看到Python 3.7及以上即可。 - Windows:到 https://www.python.org/downloads/ 下载安装,安装时勾选 “Add Python to PATH”,装完打开「命令提示符」输入
python --version。 - macOS:打开「终端」输入
python3 --version,没有的话按提示装或用brew install python。
六、完整源码(5 个文件,直接复制)
重要:这 5 个文件要放在同一个文件夹里。新建一个文件夹,命名为
wechat-dashboard,放在固定位置(例如 Linux/Mac 的~/wechat-dashboard,Windows 的D:\wechat-dashboard),以后不要移动。文件名必须一字不差(注意区分大小写、不要多
.txt后缀)。用系统自带的文本编辑器(Linux 的文本编辑器、Windows 的记事本、VS Code 等)新建文件,粘贴对应代码后保存。
文件 1:config.json(唯一需要你改动的文件)
把下面代码复制进去,把 AppID 和 AppSecret 换成你自己的,其余保持默认即可:
1
2
3
4
5
6
{
  "appid": "wx在这里填你的AppID",
  "secret": "在这里填你的AppSecret",
  "lookback_days": 7,
  "article_detail_days": 30
}
字段说明:
lookback_days:按”统计日”往回补几天,日常保持7;article_detail_days:按”发表日”取多少天内发表的文章,默认30。
文件 2:sync.py(采集脚本,核心)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
182
183
184
185
186
187
188
189
190
191
192
193
194
195
196
197
198
199
200
201
202
203
204
205
206
207
208
209
210
211
212
213
214
215
216
217
218
219
220
221
222
223
224
225
226
227
228
229
230
231
232
233
234
235
236
237
238
239
240
241
242
243
244
245
246
247
248
249
250
251
252
253
254
255
256
257
258
259
260
261
262
263
264
265
266
267
268
269
270
271
272
273
274
275
276
277
278
279
280
281
282
283
284
285
286
287
288
289
290
291
292
293
294
295
296
297
298
299
300
301
302
303
304
305
306
307
308
309
310
311
312
313
314
315
316
317
318
319
320
321
322
323
324
325
326
327
328
329
330
331
332
333
334
335
336
337
338
339
340
341
342
343
344
345
346
347
348
349
350
351
352
353
354
355
356
357
358
359
360
361
362
363
364
365
366
367
368
369
370
371
372
373
374
375
376
377
378
379
380
381
382
383
384
385
386
387
388
389
390
391
392
393
394
395
396
397
398
399
400
401
402
403
404
405
406
407
408
409
410
411
412
413
414
415
416
417
418
419
420
421
422
423
424
425
426
427
428
429
430
431
432
433
434
435
436
437
438
439
440
441
442
443
444
445
446
447
448
449
450
451
452
453
454
455
456
457
458
459
460
461
462
463
464
465
466
467
468
469
470
471
472
473
474
475
#!/usr/bin/env python3
# -*- coding: utf-8 -*-
"""
微信公众号数据看板 - 本地采集脚本(方案A,新接口版)
- 仅使用 Python 标准库,无需 pip 安装任何依赖
- 自动获取并缓存 access_token(中控,有效期 7200 秒)
- 新口径:仅「阅读人数 UV」,不再提供「阅读次数 PV」(2025-11-01 起)
- 数据来源:
  · getarticletotaldetail  按发表日取标题/链接 + 累计轨迹(还原每日增量)
  · getarticleread / share  按统计日取每篇文章阅读(含来源)/分享
  · getbizsummary           按统计日取账号级汇总(点赞/在看/留言/收藏等)
  · getusersummary / cumulate  粉丝增减 / 累计
- 累积合并到 store.json,生成 data.js 供 index.html 直接读取

适用:统信 UOS / 任意 Debian 系 Linux(Python 3.6+)
"""

import os
import sys
import re
import json
import time
from datetime import datetime, timedelta

try:
    from urllib.request import Request, urlopen
    from urllib.parse import urlencode
    from urllib.error import URLError, HTTPError
except ImportError:
    print("当前 Python 版本过低,请使用 Python 3.6 及以上版本。")
    sys.exit(1)

# ----------------------------------------------------------------------
# 路径
# ----------------------------------------------------------------------
BASE_DIR = os.path.dirname(os.path.abspath(__file__))
CONFIG_PATH = os.path.join(BASE_DIR, "config.json")
TOKEN_PATH = os.path.join(BASE_DIR, "token.json")
STORE_PATH = os.path.join(BASE_DIR, "store.json")
DATAJS_PATH = os.path.join(BASE_DIR, "data.js")

API_BASE = "https://api.weixin.qq.com"

# 按「统计日」逐日采集的接口
DAILY_ENDPOINTS = {
    "article_read": "/datacube/getarticleread",    # 每篇文章当日阅读(含来源)
    "article_share": "/datacube/getarticleshare",  # 每篇文章当日分享
    "biz_summary": "/datacube/getbizsummary",      # 账号级当日汇总
    "user_summary": "/datacube/getusersummary",    # 粉丝增减
    "user_cumulate": "/datacube/getusercumulate",  # 累计粉丝
}

# 按「发表日」采集的接口(含标题/链接与累计轨迹)
ARTICLE_DETAIL_KEY = "article_total_detail"
ARTICLE_DETAIL_ENDPOINT = "/datacube/getarticletotaldetail"

# 累计口径中可做“每日增量”的指标
ADD_METRICS = [
    "read_user", "share_user", "zaikan_user", "like_user",
    "comment_count", "collection_user", "read_subscribe_user",
]

# 新接口数据起点(早于此日期无数据)
EARLIEST_DATE = "2025-11-01"


# ----------------------------------------------------------------------
# 工具
# ----------------------------------------------------------------------
def log(msg):
    print("[%s] %s" % (datetime.now().strftime("%H:%M:%S"), msg))


def load_json(path, default):
    if not os.path.exists(path):
        return default
    try:
        with open(path, "r", encoding="utf-8") as f:
            return json.load(f)
    except Exception:
        return default


def save_json(path, data):
    tmp = path + ".tmp"
    with open(tmp, "w", encoding="utf-8") as f:
        json.dump(data, f, ensure_ascii=False, indent=2)
    os.replace(tmp, path)


def http_request(url, body=None, timeout=15):
    data = None
    headers = {"Accept": "application/json", "User-Agent": "wechat-dashboard/1.0"}
    if body is not None:
        data = json.dumps(body).encode("utf-8")
        headers["Content-Type"] = "application/json"
    req = Request(url, data=data, headers=headers,
                  method="POST" if body is not None else "GET")

    last_err = None
    for attempt in range(3):
        try:
            with urlopen(req, timeout=timeout) as resp:
                return json.loads(resp.read().decode("utf-8"))
        except HTTPError as e:
            try:
                return json.loads(e.read().decode("utf-8"))
            except Exception:
                last_err = "HTTP %s: %s" % (e.code, e.reason)
        except URLError as e:
            last_err = "网络错误: %s" % e.reason
        except Exception as e:
            last_err = "请求异常: %s" % e
        time.sleep(1.5 * (attempt + 1))
    return {"errcode": -99, "errmsg": last_err or "请求失败"}


# ----------------------------------------------------------------------
# access_token 中控
# ----------------------------------------------------------------------
def fetch_new_token(appid, secret):
    url = API_BASE + "/cgi-bin/token?" + urlencode({
        "grant_type": "client_credential",
        "appid": appid,
        "secret": secret,
    })
    result = http_request(url)
    if result.get("errcode") == 40164 or "not in whitelist" in str(result.get("errmsg", "")):
        msg = result.get("errmsg", "")
        mm = re.search(r"invalid ip\s+([0-9.]+)", msg)
        ip = mm.group(1) if mm else ""
        print("\n================ IP 白名单错误 ================")
        print("微信拒绝了取 token 的请求,因为本机出口 IP 不在白名单。")
        if ip:
            print("本机当前出口公网 IP:%s" % ip)
        print("请登录「微信公众平台 → 设置与开发 → 基本配置 → IP 白名单」")
        print("把上面的 IP 加进去(支持单 IP 或 8.8.8.8/24 这种 IP 段,不支持 8.8.8.* 写法)。")
        print("保存(约 1–2 分钟生效)后重新运行本脚本。")
        print("==============================================\n")
        sys.exit(2)
    if result.get("access_token"):
        token_info = {
            "access_token": result["access_token"],
            "expires_at": int(time.time()) + int(result.get("expires_in", 7200)) - 300,
        }
        save_json(TOKEN_PATH, token_info)
        return token_info["access_token"]
    errcode = result.get("errcode")
    errmsg = result.get("errmsg")
    if errcode in (40013, 40125):
        print("AppID 或 AppSecret 不正确,请核对 config.json。(错误码 %s)" % errcode)
    else:
        print("获取 access_token 失败:%s %s" % (errcode, errmsg))
    sys.exit(2)


def get_access_token(appid, secret, force=False):
    token_info = None if force else load_json(TOKEN_PATH, None)
    if token_info and token_info.get("access_token") and \
            int(time.time()) < int(token_info.get("expires_at", 0)):
        return token_info["access_token"]
    log("access_token 已失效或不存在,重新获取 …")
    return fetch_new_token(appid, secret)


# ----------------------------------------------------------------------
# 数据结构
# ----------------------------------------------------------------------
def new_store():
    return {
        "generated_at": "",
        "full_scan_done": False,  # 是否已完成全量标题扫描
        "collections": {},        # 合集(本地维护,亦可由浏览器同步)
        "articles": {},        # msgid -> {title, content_url, first_date}
        "article_total": {},   # msgid -> 最新累计快照
        "article_daily": {},   # stat_date -> msgid -> 当日指标
        "biz_daily": {},       # stat_date -> 账号级当日指标
        "user_daily": {},      # stat_date -> {new_user, cancel_user, cumulate_user}
    }


def ensure(d, key):
    return d.setdefault(key, {})


# ----------------------------------------------------------------------
# 合并:按统计日
# ----------------------------------------------------------------------
def merge_article_read(store, rows):
    for r in rows:
        d, m = r.get("ref_date"), r.get("msgid")
        if not d or not m:
            continue
        ensure(store["articles"], m).setdefault("first_date", d)
        detail = r.get("detail", {}) or {}
        day = ensure(ensure(store["article_daily"], d), m)
        if "read_user" in detail:
            day["read_user"] = detail["read_user"]
        src = {}
        for s in detail.get("read_user_source", []) or []:
            scene = s.get("scene_desc")
            if scene and scene != "全部":
                src[scene] = s.get("user_count", 0)
        if src:
            day["read_source"] = src


def merge_article_share(store, rows):
    for r in rows:
        d, m = r.get("ref_date"), r.get("msgid")
        if not d or not m:
            continue
        detail = r.get("detail", {}) or {}
        if "share_user" in detail:
            ensure(ensure(store["article_daily"], d), m)["share_user"] = detail["share_user"]


def merge_biz_summary(store, rows):
    for r in rows:
        d = r.get("ref_date")
        if not d:
            continue
        detail = r.get("detail", {}) or {}
        day = ensure(store["biz_daily"], d)
        for k in ("read_user", "share_user", "zaikan_user", "like_user",
                  "comment_count", "collection_user", "redirect_ori_page_user",
                  "send_page_count"):
            if k in detail:
                day[k] = detail[k]
        src = {}
        for s in detail.get("read_user_source", []) or []:
            scene = s.get("scene_desc")
            if scene and scene != "全部":
                src[scene] = s.get("user_count", 0)
        if src:
            day["read_source"] = src


def merge_user_summary(store, rows):
    agg = {}
    for r in rows:
        d = r.get("ref_date")
        if not d:
            continue
        a = agg.setdefault(d, {"new_user": 0, "cancel_user": 0})
        a["new_user"] += int(r.get("new_user", 0) or 0)
        a["cancel_user"] += int(r.get("cancel_user", 0) or 0)
    for d, val in agg.items():
        day = ensure(store["user_daily"], d)
        day["new_user"] = val["new_user"]
        day["cancel_user"] = val["cancel_user"]


def merge_user_cumulate(store, rows):
    for r in rows:
        d = r.get("ref_date")
        if d and "cumulate_user" in r:
            ensure(store["user_daily"], d)["cumulate_user"] = r["cumulate_user"]


# ----------------------------------------------------------------------
# 合并:按发表日(getarticletotaldetail)
# ----------------------------------------------------------------------
def merge_article_total_detail(store, rows):
    for r in rows:
        pub, m = r.get("ref_date"), r.get("msgid")
        if not pub or not m:
            continue
        art = ensure(store["articles"], m)
        if r.get("title"):
            art["title"] = r["title"]
        if r.get("content_url"):
            art["content_url"] = r["content_url"]
        art.setdefault("first_date", pub)

        details = sorted(r.get("detail_list", []) or [],
                         key=lambda x: x.get("stat_date", ""))
        if not details:
            continue

        prev = {k: 0 for k in ADD_METRICS}
        prev_src = {}
        for dl in details:
            sd = dl.get("stat_date")
            if not sd:
                continue
            day = ensure(ensure(store["article_daily"], sd), m)
            for k in ADD_METRICS:
                if k in dl:
                    cur = int(dl[k] or 0)
                    inc = cur - prev[k]
                    if inc < 0:
                        inc = 0
                    day[k] = inc
                    prev[k] = cur
            cur_src = {}
            for s in dl.get("read_user_source", []) or []:
                scene = s.get("scene_desc")
                if scene and scene != "全部":
                    cur_src[scene] = int(s.get("user_count", 0) or 0)
            inc_src = {}
            for scene, cur in cur_src.items():
                inc = cur - prev_src.get(scene, 0)
                if inc < 0:
                    inc = 0
                if inc:
                    inc_src[scene] = inc
            if inc_src:
                day["read_source"] = inc_src
            prev_src = cur_src

        # 最新累计快照
        last = details[-1]
        snap = ensure(store["article_total"], m)
        snap["stat_date"] = last.get("stat_date")
        for k in ("read_user", "share_user", "zaikan_user", "like_user",
                  "comment_count", "collection_user", "read_subscribe_user",
                  "read_finish_rate", "read_avg_activetime"):
            if k in last:
                snap[k] = last[k]
        src = {}
        for s in last.get("read_user_source", []) or []:
            scene = s.get("scene_desc")
            if scene and scene != "全部":
                src[scene] = int(s.get("user_count", 0) or 0)
        if src:
            snap["read_source"] = src


DAILY_MERGERS = {
    "article_read": merge_article_read,
    "article_share": merge_article_share,
    "biz_summary": merge_biz_summary,
    "user_summary": merge_user_summary,
    "user_cumulate": merge_user_cumulate,
}


# ----------------------------------------------------------------------
# 调用
# ----------------------------------------------------------------------
def call_endpoint(store, token, key, endpoint, date):
    url = API_BASE + endpoint + "?" + urlencode({"access_token": token})
    result = http_request(url, {"begin_date": date, "end_date": date})

    errcode = result.get("errcode", 0)
    if errcode == 0:
        rows = result.get("list", []) or []
        if key in DAILY_MERGERS:
            DAILY_MERGERS[key](store, rows)
        elif key == ARTICLE_DETAIL_KEY:
            merge_article_total_detail(store, rows)
        return len(rows)
    if errcode in (40001, 42001):
        return "retry"
    # 接口下线 / 不具备权限 / 数据未生成 / 日期问题 → 静默跳过
    if errcode in (47009, 47011, 48001, 61503, 61500, 61501, 40164):
        if errcode == 40164:
            log("接口 %s 提示 IP 不在白名单(40164)。" % endpoint)
        return 0
    log("接口 %s 在 %s 返回:%s %s" % (key, date, errcode, result.get("errmsg")))
    return 0


def date_range(today, n):
    ds = [(today - timedelta(days=i + 1)).strftime("%Y-%m-%d") for i in range(n)]
    return sorted(set(ds))


def main():
    config = load_json(CONFIG_PATH, {})
    appid = (config.get("appid") or "").strip()
    secret = (config.get("secret") or "").strip()
    lookback = int(config.get("lookback_days", 7))
    detail_days = int(config.get("article_detail_days", 30))

    if "--days" in sys.argv:
        idx = sys.argv.index("--days")
        try:
            val = int(sys.argv[idx + 1])
            lookback = val
            detail_days = max(detail_days, val)
        except Exception:
            pass

    if not appid or not secret or appid.startswith("wx在"):
        print("请先编辑 config.json,填入你的 appid 和 secret。")
        sys.exit(1)

    log("开始采集:统计日回溯 %s 天,发表日回溯 %s 天。" % (lookback, detail_days))
    store = load_json(STORE_PATH, new_store())
    if not isinstance(store, dict) or "article_daily" not in store:
        store = new_store()

    token = get_access_token(appid, secret)
    today = datetime.now().date()

    # 1) 按发表日:标题/链接 + 累计轨迹(默认 30 天)
    pub_dates = date_range(today, detail_days)
    n_pub = 0
    for date in pub_dates:
        n = call_endpoint(store, token, ARTICLE_DETAIL_KEY, ARTICLE_DETAIL_ENDPOINT, date)
        if n == "retry":
            token = get_access_token(appid, secret, force=True)
            n = call_endpoint(store, token, ARTICLE_DETAIL_KEY, ARTICLE_DETAIL_ENDPOINT, date)
        if isinstance(n, int):
            n_pub += n
        time.sleep(0.12)
    log("发表内容明细完成(%s 天)" % len(pub_dates))

    # 1.1) 全量标题扫描:首次(或加 --full)逐日回溯到新接口起点,
    #      彻底修复老文章标题只显示“文章 xxxxx_1”的问题
    force_full = "--full" in sys.argv
    if force_full or not store.get("full_scan_done"):
        earliest = datetime.strptime(EARLIEST_DATE, "%Y-%m-%d").date()
        start = today - timedelta(days=365)
        if start < earliest:
            start = earliest
        all_dates = []
        cur = start
        yesterday = today - timedelta(days=1)
        while cur <= yesterday:
            all_dates.append(cur.strftime("%Y-%m-%d"))
            cur += timedelta(days=1)
        log("开始全量标题扫描:%s 至 %s(共 %s 天,首次约数分钟,期间请勿中断)"
            % (all_dates[0], all_dates[-1], len(all_dates)))
        for i, date in enumerate(all_dates):
            n = call_endpoint(store, token, ARTICLE_DETAIL_KEY,
                              ARTICLE_DETAIL_ENDPOINT, date)
            if n == "retry":
                token = get_access_token(appid, secret, force=True)
                n = call_endpoint(store, token, ARTICLE_DETAIL_KEY,
                                  ARTICLE_DETAIL_ENDPOINT, date)
            time.sleep(0.05)
            if (i + 1) % 30 == 0:
                log("  全量扫描进度 %s/%s" % (i + 1, len(all_dates)))
        store["full_scan_done"] = True
        log("全量标题扫描完成。")

    # 2) 按统计日:每日端点
    stat_dates = date_range(today, lookback)
    n_stat = 0
    for date in stat_dates:
        for key, endpoint in DAILY_ENDPOINTS.items():
            n = call_endpoint(store, token, key, endpoint, date)
            if n == "retry":
                token = get_access_token(appid, secret, force=True)
                n = call_endpoint(store, token, key, endpoint, date)
            if isinstance(n, int):
                n_stat += n
            time.sleep(0.12)
        log("  %s 完成" % date)

    store["generated_at"] = datetime.now().strftime("%Y-%m-%d %H:%M:%S")
    save_json(STORE_PATH, store)

    payload = (
        "window.DATA = " + json.dumps(store, ensure_ascii=False) + ";\n"
        + "window.DATA_GENERATED_AT = " + json.dumps(store["generated_at"], ensure_ascii=False) + ";\n"
    )
    with open(DATAJS_PATH, "w", encoding="utf-8") as f:
        f.write(payload)

    log("采集完成:发表明细 %s 条、每日记录 %s 条。" % (n_pub, n_stat))
    log("已写入 store.json / data.js,用浏览器打开 index.html 即可。")


if __name__ == "__main__":
    try:
        main()
    except KeyboardInterrupt:
        print("\n已取消。")
        sys.exit(1)
    except BrokenPipeError:
        pass
文件 3:run.sh(一键运行,Linux / macOS)
Windows 用户不用建这个文件,直接用命令
python sync.py即可。
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
#!/usr/bin/env bash
# 微信公众号数据看板 - 一键采集脚本(统信 UOS / Linux)
# 用法:
#   ./run.sh            按 config.json 中的 lookback_days 采集
#   ./run.sh --days 30  首次运行时手动指定回溯 30 天

set -u
cd "$(dirname "$0")"

if ! command -v python3 >/dev/null 2>&1; then
  echo "未检测到 python3。统信 UOS 一般自带;若没有,请在「应用商店」安装或执行:sudo apt install python3"
  exit 1
fi

PYVER=$(python3 -c 'import sys;print("%d.%d"%sys.version_info[:2])')
echo "使用 Python 版本:$PYVER"
python3 sync.py "$@"
文件 4:index.html(数据看板,双击打开)
这是最长的一个文件,从头到尾完整复制、不要漏行:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
182
183
184
185
186
187
188
189
190
191
192
193
194
195
196
197
198
199
200
201
202
203
204
205
206
207
208
209
210
211
212
213
214
215
216
217
218
219
220
221
222
223
224
225
226
227
228
229
230
231
232
233
234
235
236
237
238
239
240
241
242
243
244
245
246
247
248
249
250
251
252
253
254
255
256
257
258
259
260
261
262
263
264
265
266
267
268
269
270
271
272
273
274
275
276
277
278
279
280
281
282
283
284
285
286
287
288
289
290
291
292
293
294
295
296
297
298
299
300
301
302
303
304
305
306
307
308
309
310
311
312
313
314
315
316
317
318
319
320
321
322
323
324
325
326
327
328
329
330
331
332
333
334
335
336
337
338
339
340
341
342
343
344
345
346
347
348
349
350
351
352
353
354
355
356
357
358
359
360
361
362
363
364
365
366
367
368
369
370
371
372
373
374
375
376
377
378
379
380
381
382
383
384
385
386
387
388
389
390
391
392
393
394
395
396
397
398
399
400
401
402
403
404
405
406
407
408
409
410
411
412
413
414
415
416
417
418
419
420
421
422
423
424
425
426
427
428
429
430
431
432
433
434
435
436
437
438
439
440
441
442
443
444
445
446
447
448
449
450
451
452
453
454
455
456
457
458
459
460
461
462
463
464
465
466
467
468
469
470
471
472
473
474
475
476
477
478
479
480
481
482
483
484
485
486
487
488
489
490
491
492
493
494
495
496
497
498
499
500
501
502
503
504
505
506
507
508
509
510
511
512
513
514
515
516
517
518
519
520
521
522
523
524
525
526
527
528
529
530
531
532
533
534
535
536
537
538
539
540
541
542
543
544
545
546
547
548
549
550
551
552
553
554
555
556
557
558
559
560
561
562
563
564
565
566
567
568
569
570
571
572
573
574
575
576
577
578
579
580
581
582
583
584
585
586
587
588
589
590
591
592
593
594
595
596
597
598
599
600
601
602
603
604
605
606
607
608
609
610
611
612
613
614
615
616
617
618
619
620
621
622
623
624
625
626
627
628
629
630
631
632
633
634
635
636
637
638
639
640
641
642
643
644
645
646
647
648
649
650
651
652
653
654
655
656
657
658
659
660
661
662
663
664
665
666
667
668
669
670
671
672
673
674
675
676
677
678
679
680
681
682
683
684
685
686
687
688
689
690
691
692
693
694
695
696
697
698
699
700
701
702
703
704
705
706
707
708
709
710
711
712
713
714
715
716
717
718
719
720
721
722
723
724
725
726
727
728
729
730
731
732
733
734
735
736
737
738
739
740
741
742
743
744
745
746
747
748
749
750
751
752
753
754
755
756
757
758
759
760
761
762
763
764
765
766
767
768
769
770
771
772
773
774
775
776
777
778
779
780
781
782
783
784
785
786
787
788
789
790
791
792
793
794
795
796
797
798
799
800
801
802
803
804
805
806
807
808
809
810
811
812
813
814
815
816
817
818
819
820
821
822
823
824
825
826
827
828
829
830
831
832
833
834
835
836
837
838
839
840
841
842
843
844
845
846
847
848
849
850
851
852
853
854
855
856
857
858
859
860
861
862
863
864
865
866
867
868
869
870
871
872
873
874
875
876
877
878
879
880
881
882
883
884
885
886
887
<!DOCTYPE html>
<html lang="zh-CN">
<head>
<meta charset="UTF-8" />
<meta name="viewport" content="width=device-width, initial-scale=1.0" />
<title>公众号数据看板</title>
<link rel="icon" href="data:image/svg+xml,%3Csvg xmlns='http://www.w3.org/2000/svg' viewBox='0 0 24 24'%3E%3Crect width='24' height='24' rx='5' fill='%232563eb'/%3E%3Cpath d='M7 14l3-4 2.5 2.5L16 7' stroke='white' stroke-width='2' fill='none' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/svg%3E" />
<script src="https://cdn.jsdelivr.net/npm/echarts@5.5.0/dist/echarts.min.js"></script>
<script src="https://cdn.jsdelivr.net/npm/xlsx@0.18.5/dist/xlsx.full.min.js"></script>
<style>
:root {
--blue: #2563eb;
--teal: #0d9488;
--green: #16a34a;
--amber: #d97706;
--red: #dc2626;
--ink: #0f172a;
--muted: #64748b;
--line: #e2e8f0;
--bg: #f1f5f9;
--card: #ffffff;
}
* { box-sizing: border-box; margin: 0; padding: 0; }
body {
font-family: -apple-system, "PingFang SC", "Microsoft YaHei", "Noto Sans CJK SC", sans-serif;
background: var(--bg);
color: var(--ink);
line-height: 1.5;
padding: 20px;
}
.wrap { max-width: 1280px; margin: 0 auto; }
header {
display: flex; flex-wrap: wrap; align-items: baseline; gap: 12px;
margin-bottom: 18px;
}
header h1 { font-size: 22px; font-weight: 700; }
header .sub { color: var(--muted); font-size: 13px; }
.kpis {
display: grid;
grid-template-columns: repeat(auto-fit, minmax(160px, 1fr));
gap: 14px; margin-bottom: 16px;
}
.kpi {
background: var(--card); border: 1px solid var(--line); border-radius: 12px;
padding: 16px; box-shadow: 0 1px 2px rgba(15,23,42,.04);
}
.kpi .label { font-size: 13px; color: var(--muted); margin-bottom: 6px; }
.kpi .value { font-size: 26px; font-weight: 700; letter-spacing: -.5px; }
.kpi .value small { font-size: 14px; font-weight: 500; color: var(--muted); margin-left: 2px; }
.kpi .delta { font-size: 12px; margin-top: 4px; }
.up { color: var(--green); }
.down { color: var(--red); }
.grid {
display: grid; grid-template-columns: repeat(2, 1fr); gap: 16px; margin-bottom: 16px;
}
.card {
background: var(--card); border: 1px solid var(--line); border-radius: 12px;
padding: 16px 16px 8px; box-shadow: 0 1px 2px rgba(15,23,42,.04);
}
.card h3 { font-size: 15px; font-weight: 600; margin-bottom: 4px; }
.card .hint { font-size: 12px; color: var(--muted); margin-bottom: 8px; }
.chart { width: 100%; height: 320px; }
.card.span2 { grid-column: span 2; }
/* 工具栏 */
.toolbar {
display: flex; flex-wrap: wrap; gap: 10px; align-items: center;
padding: 10px 0 12px; border-bottom: 1px solid var(--line); margin-bottom: 4px;
}
.toolbar .grow { flex: 1; min-width: 120px; }
.toolbar input[type=date], .toolbar select, .toolbar input[type=text] {
height: 34px; padding: 0 10px; border: 1px solid var(--line); border-radius: 8px;
font-size: 13px; color: var(--ink); background: #fff; min-width: 0;
}
.toolbar input[type=text] { width: 180px; }
.toolbar .sep { color: var(--muted); font-size: 13px; }
.btn {
height: 34px; padding: 0 14px; border-radius: 8px; border: 1px solid var(--line);
background: #fff; color: var(--ink); font-size: 13px; cursor: pointer; white-space: nowrap;
}
.btn:hover { border-color: #cbd5e1; background: #f8fafc; }
.btn.primary { background: var(--blue); border-color: var(--blue); color: #fff; }
.btn.primary:hover { background: #1d4ed8; }
.btn.teal { background: var(--teal); border-color: var(--teal); color: #fff; }
.btn.teal:hover { background: #0f766e; }
.toolbar .count { font-size: 12px; color: var(--muted); margin-left: auto; }
table { width: 100%; border-collapse: collapse; font-size: 13px; }
thead th {
text-align: left; color: var(--muted); font-weight: 600; font-size: 12px;
padding: 10px 12px; border-bottom: 1px solid var(--line); white-space: nowrap;
user-select: none;
}
thead th.sortable { cursor: pointer; }
thead th.sortable:hover { color: var(--ink); }
thead th .arrow { font-size: 10px; margin-left: 3px; color: var(--blue); }
tbody td { padding: 10px 12px; border-bottom: 1px solid #f1f5f9; vertical-align: middle; }
tbody tr:hover { background: #f8fafc; }
td.title { max-width: 320px; }
td.title a { color: var(--ink); text-decoration: none; }
td.title a:hover { color: var(--blue); }
.num { text-align: right; font-variant-numeric: tabular-nums; white-space: nowrap; }
.table-wrap { max-height: 560px; overflow: auto; }
.tag {
display: inline-block; font-size: 11px; line-height: 18px; padding: 0 8px;
background: #ecfdf5; color: #047857; border: 1px solid #a7f3d0; border-radius: 20px;
margin: 1px 3px 1px 0; white-space: nowrap;
}
.coll-cell { cursor: pointer; min-width: 130px; }
.coll-cell .add { color: #94a3b8; font-size: 12px; }
.coll-cell:hover .add { color: var(--blue); }
/* 弹层 */
.popover {
position: fixed; z-index: 60; background: #fff; border: 1px solid var(--line);
border-radius: 10px; box-shadow: 0 12px 30px rgba(15,23,42,.18); padding: 8px;
width: 220px; max-height: 300px; overflow: auto;
}
.popover .pitem { display: flex; align-items: center; gap: 8px; padding: 6px 8px; border-radius: 6px; font-size: 13px; cursor: pointer; }
.popover .pitem:hover { background: #f8fafc; }
.popover .pitem input { margin: 0; }
.popover .pnew { display: flex; gap: 6px; padding: 8px 8px 4px; border-top: 1px solid var(--line); margin-top: 6px; }
.popover .pnew input { flex: 1; height: 30px; border: 1px solid var(--line); border-radius: 6px; padding: 0 8px; font-size: 12px; }
.popover .pnew button { height: 30px; border: none; background: var(--blue); color: #fff; border-radius: 6px; padding: 0 10px; font-size: 12px; cursor: pointer; }
.popover .pempty { font-size: 12px; color: var(--muted); padding: 6px 8px; }
/* 模态框 */
.overlay {
position: fixed; inset: 0; z-index: 50; background: rgba(15,23,42,.45);
display: none; align-items: center; justify-content: center; padding: 20px;
}
.overlay.show { display: flex; }
.modal {
background: #fff; border-radius: 14px; width: 560px; max-width: 100%; max-height: 88vh;
display: flex; flex-direction: column; overflow: hidden;
}
.modal .mhead { display: flex; align-items: center; justify-content: space-between; padding: 16px 18px; border-bottom: 1px solid var(--line); }
.modal .mhead h3 { font-size: 16px; }
.modal .mhead .x { border: none; background: none; font-size: 20px; color: var(--muted); cursor: pointer; }
.modal .mbody { padding: 16px 18px; overflow: auto; }
.modal .mnote { font-size: 12px; color: var(--muted); background: #f8fafc; border: 1px solid var(--line); border-radius: 8px; padding: 8px 10px; margin-bottom: 12px; }
.modal .mcreate { display: flex; gap: 8px; margin-bottom: 14px; }
.modal .mcreate input { flex: 1; height: 36px; border: 1px solid var(--line); border-radius: 8px; padding: 0 12px; font-size: 13px; }
.modal .crow { display: flex; align-items: center; gap: 10px; padding: 10px 4px; border-bottom: 1px solid #f1f5f9; }
.modal .crow .cname { flex: 1; font-size: 13px; }
.modal .crow .ccnt { font-size: 12px; color: var(--muted); }
.modal .crow button { border: none; background: none; color: var(--muted); font-size: 12px; cursor: pointer; }
.modal .crow button:hover { color: var(--ink); }
.modal .crow button.del:hover { color: var(--red); }
.modal .mfoot { display: flex; gap: 8px; padding: 12px 18px; border-top: 1px solid var(--line); }
.empty {
background: var(--card); border: 1px dashed var(--line); border-radius: 12px;
padding: 60px 20px; text-align: center; color: var(--muted);
}
.empty code {
background: #f1f5f9; padding: 2px 8px; border-radius: 6px; color: var(--ink);
}
footer { color: var(--muted); font-size: 12px; text-align: center; margin: 20px 0 8px; }
@media (max-width: 860px) {
.grid { grid-template-columns: 1fr; }
.card.span2 { grid-column: span 1; }
body { padding: 12px; }
.chart { height: 280px; }
.toolbar input[type=text] { width: 100%; }
.toolbar .count { margin-left: 0; width: 100%; }
}
</style>
</head>
<body>
<div class="wrap">
<header>
<h1>公众号数据看板</h1>
<span class="sub" id="generated"></span>
</header>
<div id="view">
<div class="kpis" id="kpis"></div>
<div class="grid">
<div class="card span2">
<h3>阅读 / 分享趋势</h3>
<div class="hint">按统计日期汇总的阅读人数与分享人数(新口径仅统计人数,无次数)</div>
<div id="c-trend" class="chart"></div>
</div>
</div>
<div class="grid">
<div class="card">
<h3>粉丝增长</h3>
<div class="hint">每日新增 / 取关(柱)与累计关注(线)</div>
<div id="c-fans" class="chart"></div>
</div>
<div class="card">
<h3>阅读来源构成</h3>
<div class="hint">统计周期内各场景阅读人数占比</div>
<div id="c-source" class="chart"></div>
</div>
</div>
<div class="grid">
<div class="card span2">
<h3>文章阅读榜 · Top 10</h3>
<div class="hint">按累计阅读人数排序</div>
<div id="c-rank" class="chart" style="height:380px;"></div>
</div>
</div>
<div class="grid">
<div class="card span2">
<h3>文章明细</h3>
<div class="toolbar">
<input type="date" id="f-start" />
<span class="sep">至</span>
<input type="date" id="f-end" />
<select id="f-coll">
<option value="">全部合集</option>
<option value="__none__">未归合集</option>
</select>
<input type="text" id="f-q" placeholder="搜索标题" />
<button class="btn" id="f-reset">重置</button>
<span class="grow"></span>
<button class="btn" id="btn-manage-coll">管理合集</button>
<button class="btn teal" id="btn-xls-30">下载近30天Excel</button>
<button class="btn primary" id="btn-xls-all">下载全部Excel</button>
<span class="count" id="f-count"></span>
</div>
<div class="table-wrap">
<table>
<thead>
<tr id="head-row">
<th class="sortable" data-key="title">标题<span class="arrow"></span></th>
<th class="sortable" data-key="pubdate">发表日期<span class="arrow"></span></th>
<th data-key="coll">合集</th>
<th class="sortable num" data-key="read">阅读<span class="arrow"></span></th>
<th class="sortable num" data-key="share">分享<span class="arrow"></span></th>
<th class="sortable num" data-key="fav">收藏<span class="arrow"></span></th>
<th class="sortable num" data-key="like">点赞<span class="arrow"></span></th>
<th class="sortable num" data-key="zaikan">在看<span class="arrow"></span></th>
<th class="sortable num" data-key="comment">留言<span class="arrow"></span></th>
</tr>
</thead>
<tbody id="tbody"></tbody>
</table>
</div>
</div>
</div>
</div>
<div class="empty" id="empty" style="display:none;">
<p style="font-size:16px;color:var(--ink);margin-bottom:10px;">还没有数据</p>
<p>请先在当前文件夹打开终端,运行 <code>python3 sync.py</code> 完成一次采集,<br/>再刷新本页面。</p>
</div>
<footer>数据由本地脚本定时采集自微信公众平台 · 仅存储在本机,不上传任何第三方</footer>
</div>
<!-- 合集归属弹层 -->
<div class="popover" id="coll-pop" style="display:none;"></div>
<!-- 合集管理模态框 -->
<div class="overlay" id="coll-overlay">
<div class="modal">
<div class="mhead">
<h3>管理合集</h3>
<button class="x" id="m-close">×</button>
</div>
<div class="mbody">
<div class="mnote">微信未开放“合集”接口,无法自动同步后台合集;这里的合集为<b>本看板本地分组</b>,保存在当前浏览器,可在明细表中筛选,并随 Excel 一起导出。</div>
<div class="mcreate">
<input type="text" id="m-new-name" placeholder="输入新合集名称,回车创建" />
<button class="btn primary" id="m-create-btn">创建</button>
</div>
<div id="m-list"></div>
</div>
<div class="mfoot">
<button class="btn" id="m-export">备份合集(JSON)</button>
<button class="btn" id="m-import">导入备份</button>
<input type="file" id="m-import-file" accept="application/json" style="display:none;" />
</div>
</div>
</div>
<script src="data.js"></script>
<script>
(function () {
var D = window.DATA;
if (!D || (Object.keys(D.articles || {}).length === 0 &&
Object.keys(D.article_daily || {}).length === 0 &&
Object.keys(D.biz_daily || {}).length === 0 &&
Object.keys(D.user_daily || {}).length === 0)) {
document.getElementById('view').style.display = 'none';
document.getElementById('empty').style.display = 'block';
return;
}
var articles = D.articles || {};
var articleTotal = D.article_total || {};
var articleDaily = D.article_daily || {};
var bizDaily = D.biz_daily || {};
var userDaily = D.user_daily || {};
var COLORS = ['#2563eb','#0d9488','#16a34a','#d97706','#dc2626','#7c3aed','#0891b2','#65a30d'];
function fmt(n) {
n = n || 0;
if (n >= 100000000) return (n / 100000000).toFixed(2) + '亿';
if (n >= 10000) return (n / 10000).toFixed(1) + '万';
return String(n);
}
function int(n) { return n == null ? 0 : Math.round(n); }
function esc(s) {
return String(s == null ? '' : s).replace(/[&<>"']/g, function (c) {
return { '&': '&', '<': '<', '>': '>', '"': '"', "'": ''' }[c];
});
}
var dateSet = {};
Object.keys(articleDaily).forEach(function (d) { dateSet[d] = 1; });
Object.keys(bizDaily).forEach(function (d) { dateSet[d] = 1; });
Object.keys(userDaily).forEach(function (d) { dateSet[d] = 1; });
var dates = Object.keys(dateSet).sort();
function shortDate(d) { return d.slice(5); }
// ---------------- 合集(本地,localStorage)----------------
var COLL_KEY = 'wechat_collections_v1';
function loadCollections() {
try {
var x = JSON.parse(localStorage.getItem(COLL_KEY));
return x && typeof x === 'object' ? x : {};
} catch (e) { return {}; }
}
var collections = loadCollections();
function saveCollections() {
try { localStorage.setItem(COLL_KEY, JSON.stringify(collections)); } catch (e) {}
}
function collIdsOf(mid) {
var out = [];
Object.keys(collections).forEach(function (cid) {
if ((collections[cid].article_ids || []).indexOf(mid) >= 0) out.push(cid);
});
return out;
}
function toggleColl(cid, mid) {
var c = collections[cid];
if (!c) return;
c.article_ids = c.article_ids || [];
var i = c.article_ids.indexOf(mid);
if (i >= 0) c.article_ids.splice(i, 1); else c.article_ids.push(mid);
saveCollections();
}
function createCollection(name) {
name = (name || '').trim();
if (!name) return null;
var cid = 'c' + Date.now() + Math.floor(Math.random() * 1000);
collections[cid] = { name: name, created: new Date().toISOString(), article_ids: [] };
saveCollections();
return cid;
}
// ---------------- 每日汇总 ----------------
function dailyArticleSum(date) {
var o = { ru: 0, su: 0 };
Object.keys(articleDaily[date] || {}).forEach(function (m) {
var x = articleDaily[date][m];
o.ru += int(x.read_user);
o.su += int(x.share_user);
});
return o;
}
var trend = dates.map(function (d) {
var biz = bizDaily[d] || {};
var s = dailyArticleSum(d);
return {
date: d,
ru: biz.read_user != null ? int(biz.read_user) : s.ru,
su: biz.share_user != null ? int(biz.share_user) : s.su
};
});
var fans = dates.map(function (d) {
var u = userDaily[d] || {};
return { date: d, cum: u.cumulate_user == null ? null : int(u.cumulate_user),
newer: int(u.new_user), cancel: int(u.cancel_user) };
});
var sourceAgg = {};
dates.forEach(function (d) {
var rs = (bizDaily[d] || {}).read_source;
if (!rs) return;
Object.keys(rs).forEach(function (k) { sourceAgg[k] = (sourceAgg[k] || 0) + int(rs[k]); });
});
if (!Object.keys(sourceAgg).length) {
dates.forEach(function (d) {
Object.keys(articleDaily[d] || {}).forEach(function (m) {
var rs = articleDaily[d][m].read_source || {};
Object.keys(rs).forEach(function (k) { sourceAgg[k] = (sourceAgg[k] || 0) + int(rs[k]); });
});
});
}
var dailyByArticle = {};
Object.keys(articleDaily).forEach(function (d) {
Object.keys(articleDaily[d]).forEach(function (m) {
var x = articleDaily[d][m];
var a = dailyByArticle[m] || (dailyByArticle[m] = { read: 0, share: 0, fav: 0 });
a.read += int(x.read_user);
a.share += int(x.share_user);
a.fav += int(x.collection_user);
});
});
var idSet = {};
Object.keys(articles).forEach(function (m) { idSet[m] = 1; });
Object.keys(articleTotal).forEach(function (m) { idSet[m] = 1; });
Object.keys(dailyByArticle).forEach(function (m) { idSet[m] = 1; });
var articleRows = Object.keys(idSet).map(function (m) {
var meta = articles[m] || {};
var tot = articleTotal[m] || {};
var dai = dailyByArticle[m] || {};
return {
id: m,
title: meta.title || ('文章 ' + m),
url: meta.content_url || '',
pubdate: meta.first_date || '',
read: tot.read_user || dai.read || 0,
share: tot.share_user || dai.share || 0,
fav: tot.collection_user || dai.fav || 0,
like: int(tot.like_user),
zaikan: int(tot.zaikan_user),
comment: int(tot.comment_count)
};
});
// ---------------- 筛选 / 排序状态 ----------------
var state = { start: '', end: '', coll: '', q: '', sortKey: 'pubdate', sortDir: 'desc' };
function sortRows(rows) {
var k = state.sortKey, dir = state.sortDir === 'asc' ? 1 : -1;
rows.sort(function (a, b) {
var va, vb;
if (k === 'title') {
return dir * a.title.localeCompare(b.title, 'zh-Hans-CN');
}
if (k === 'pubdate') {
va = a.pubdate || '0'; vb = b.pubdate || '0';
return dir * (va < vb ? -1 : va > vb ? 1 : 0);
}
if (k === 'coll') {
va = collIdsOf(a.id).length; vb = collIdsOf(b.id).length;
return dir * (va - vb);
}
va = int(a[k]); vb = int(b[k]);
return dir * (va - vb);
});
return rows;
}
function filteredRows() {
var rows = articleRows.filter(function (r) {
if (state.q && r.title.toLowerCase().indexOf(state.q.toLowerCase()) < 0) return false;
if (state.coll === '__none__') {
if (collIdsOf(r.id).length) return false;
} else if (state.coll) {
if (collIdsOf(r.id).indexOf(state.coll) < 0) return false;
}
if (state.start && (!r.pubdate || r.pubdate < state.start)) return false;
if (state.end && (!r.pubdate || r.pubdate > state.end)) return false;
return true;
});
return sortRows(rows);
}
// ---------------- Excel 导出 ----------------
function rowsForExcel(scope) {
var rows;
if (scope === '30') {
var d = new Date();
d.setDate(d.getDate() - 30);
var cutoff = d.toISOString().slice(0, 10);
rows = articleRows.filter(function (r) { return r.pubdate && r.pubdate >= cutoff; });
} else {
rows = articleRows.slice();
}
return sortRows(rows);
}
function downloadExcel(scope) {
if (!window.XLSX) { alert('Excel 库未加载,请联网后刷新页面。'); return; }
var rows = rowsForExcel(scope);
if (!rows.length) { alert('当前范围没有可导出的文章。'); return; }
var data = rows.map(function (r) {
return {
'发表日期': r.pubdate || '',
'标题': r.title,
'合集': collIdsOf(r.id).map(function (c) { return (collections[c] || {}).name || ''; }).join('、'),
'阅读人数': int(r.read),
'分享人数': int(r.share),
'收藏人数': int(r.fav),
'点赞人数': int(r.like),
'在看人数': int(r.zaikan),
'留言数': int(r.comment),
'链接': r.url
};
});
var ws = XLSX.utils.json_to_sheet(data);
ws['!cols'] = [{wch:12},{wch:42},{wch:18},{wch:10},{wch:10},{wch:10},{wch:10},{wch:10},{wch:8},{wch:34}];
var wb = XLSX.utils.book_new();
XLSX.utils.book_append_sheet(wb, ws, '文章明细');
var stamp = new Date().toISOString().slice(0, 10);
XLSX.writeFile(wb, scope === '30'
? ('公众号文章明细_近30天_' + stamp + '.xlsx')
: ('公众号文章明细_全部_' + stamp + '.xlsx'));
}
// ---------------- KPI ----------------
var last7 = dates.slice(-7);
var sum7ru = 0, sum7su = 0;
last7.forEach(function (d) {
var t = trend.find(function (x) { return x.date === d; });
if (t) { sum7ru += t.ru; sum7su += t.su; }
});
var cumList = fans.filter(function (f) { return f.cum != null; });
var latestCum = cumList.length ? cumList[cumList.length - 1] : null;
var latestDay = fans.length ? fans[fans.length - 1] : null;
var net = latestDay ? latestDay.newer - latestDay.cancel : 0;
var kpi = [
{ label: '累计粉丝', value: fmt(latestCum ? latestCum.cum : 0),
delta: latestDay ? ('最新日 ' + shortDate(latestDay.date)) : '' },
{ label: '最新日净增', value: (net >= 0 ? '+' : '') + fmt(net),
cls: net >= 0 ? 'up' : 'down',
delta: latestDay ? ('新增 ' + fmt(latestDay.newer) + ' · 取关 ' + fmt(latestDay.cancel)) : '' },
{ label: '近7天阅读人数', value: fmt(sum7ru), delta: 'UV' },
{ label: '近7天分享人数', value: fmt(sum7su), delta: '人' },
{ label: '文章总数', value: fmt(articleRows.length), delta: '篇' }
];
document.getElementById('kpis').innerHTML = kpi.map(function (k) {
return '<div class="kpi"><div class="label">' + k.label + '</div>' +
'<div class="value ' + (k.cls || '') + '">' + k.value +
(k.delta && k.delta.length <= 4 ? '<small>' + k.delta + '</small>' : '') +
'</div>' +
(k.delta && k.delta.length > 4 ? '<div class="delta ' + (k.cls || '') + '">' + k.delta + '</div>' : '') +
'</div>';
}).join('');
document.getElementById('generated').textContent =
'数据更新时间:' + (D.generated_at || window.DATA_GENERATED_AT || '未知');
// ---------------- 图表 ----------------
var baseAxis = {
axisLine: { lineStyle: { color: '#cbd5e1' } },
axisLabel: { color: '#64748b', fontSize: 11 },
splitLine: { lineStyle: { color: '#f1f5f9' } }
};
var charts = [];
function makeChart(id, option) {
if (!window.echarts) {
document.getElementById(id).innerHTML =
'<div style="height:100%;display:flex;align-items:center;justify-content:center;color:#94a3b8;font-size:13px;">图表库未加载(可能离线),请联网后刷新</div>';
return;
}
var c = echarts.init(document.getElementById(id));
c.setOption(option);
charts.push(c);
}
makeChart('c-trend', {
color: ['#2563eb', '#0d9488'],
tooltip: { trigger: 'axis' },
legend: { data: ['阅读人数', '分享人数'], top: 0, right: 0, textStyle: { color: '#475569' } },
grid: { left: 50, right: 20, top: 36, bottom: 40 },
xAxis: Object.assign({ type: 'category', data: dates.map(shortDate), boundaryGap: false }, baseAxis),
yAxis: Object.assign({ type: 'value', axisLabel: { formatter: fmt, color: '#64748b' } }, baseAxis),
dataZoom: dates.length > 15 ? [{ type: 'inside' }, { type: 'slider', height: 18, bottom: 8 }] : [],
series: [
{ name: '阅读人数', type: 'line', smooth: true, showSymbol: false,
lineStyle: { width: 3 }, areaStyle: { color: 'rgba(37,99,235,.08)' },
data: trend.map(function (t) { return t.ru; }) },
{ name: '分享人数', type: 'line', smooth: true, showSymbol: false,
lineStyle: { width: 2 },
data: trend.map(function (t) { return t.su; }) }
]
});
makeChart('c-fans', {
color: ['#16a34a', '#dc2626', '#2563eb'],
tooltip: { trigger: 'axis' },
legend: { data: ['新增', '取关', '累计粉丝'], top: 0, right: 0, textStyle: { color: '#475569' } },
grid: { left: 56, right: 56, top: 36, bottom: 40 },
xAxis: Object.assign({ type: 'category', data: dates.map(shortDate) }, baseAxis),
yAxis: [
Object.assign({ type: 'value', name: '增减', axisLabel: { color: '#64748b' } }, baseAxis),
Object.assign({ type: 'value', name: '累计', axisLabel: { formatter: fmt, color: '#64748b' } }, baseAxis)
],
series: [
{ name: '新增', type: 'bar', data: fans.map(function (f) { return f.newer; }) },
{ name: '取关', type: 'bar', data: fans.map(function (f) { return -f.cancel; }) },
{ name: '累计粉丝', type: 'line', smooth: true, yAxisIndex: 1, showSymbol: false,
lineStyle: { width: 3 }, data: fans.map(function (f) { return f.cum; }) }
]
});
var sourceData = Object.keys(sourceAgg).map(function (k) {
return { name: k, value: sourceAgg[k] };
}).sort(function (a, b) { return b.value - a.value; });
if (!sourceData.length) {
document.getElementById('c-source').innerHTML =
'<div style="height:100%;display:flex;align-items:center;justify-content:center;color:#94a3b8;font-size:13px;">暂无来源数据</div>';
} else {
makeChart('c-source', {
color: COLORS,
tooltip: { trigger: 'item', formatter: function (p) { return p.name + ':' + fmt(p.value) + '(' + p.percent + '%)'; } },
legend: { type: 'scroll', bottom: 0, textStyle: { color: '#475569' } },
series: [{
type: 'pie', radius: ['42%', '68%'], center: ['50%', '45%'],
itemStyle: { borderColor: '#fff', borderWidth: 2 },
label: { show: false },
data: sourceData
}]
});
}
var rankSorted = articleRows.slice().sort(function (a, b) { return b.read - a.read; });
var top10 = rankSorted.slice(0, 10).reverse();
makeChart('c-rank', {
color: ['#0d9488'],
tooltip: { trigger: 'axis', axisPointer: { type: 'shadow' },
formatter: function (p) { var r = p[0]; return esc(r.name) + '<br/>阅读:' + fmt(r.value); } },
grid: { left: 8, right: 40, top: 10, bottom: 10, containLabel: true },
xAxis: Object.assign({ type: 'value', axisLabel: { formatter: fmt, color: '#64748b' } }, baseAxis),
yAxis: Object.assign({ type: 'category',
data: top10.map(function (r) { return r.title.length > 18 ? r.title.slice(0, 18) + '…' : r.title; }),
axisLabel: { color: '#334155', fontSize: 11 } }, baseAxis),
series: [{
type: 'bar', data: top10.map(function (r) { return r.read; }),
barMaxWidth: 22, itemStyle: { borderRadius: [0, 4, 4, 0] },
label: { show: true, position: 'right', formatter: function (p) { return fmt(p.value); }, color: '#475569' }
}]
});
// ---------------- 表格渲染 ----------------
function collTagsHtml(r) {
var ids = collIdsOf(r.id);
if (!ids.length) return '<span class="add">+ 归类</span>';
return ids.map(function (cid) {
return '<span class="tag">' + esc((collections[cid] || {}).name || '') + '</span>';
}).join('');
}
function updateArrows() {
document.querySelectorAll('#head-row th.sortable').forEach(function (th) {
var sp = th.querySelector('.arrow');
sp.textContent = th.getAttribute('data-key') === state.sortKey
? (state.sortDir === 'asc' ? '▲' : '▼') : '';
});
}
function renderTable() {
var rows = filteredRows();
document.getElementById('tbody').innerHTML = rows.map(function (r) {
var title = r.url
? '<a href="' + esc(r.url) + '" target="_blank" rel="noopener">' + esc(r.title) + '</a>'
: esc(r.title);
return '<tr>' +
'<td class="title">' + title + '</td>' +
'<td>' + (r.pubdate || '—') + '</td>' +
'<td class="coll-cell" data-mid="' + esc(r.id) + '">' + collTagsHtml(r) + '</td>' +
'<td class="num">' + fmt(r.read) + '</td>' +
'<td class="num">' + fmt(r.share) + '</td>' +
'<td class="num">' + fmt(r.fav) + '</td>' +
'<td class="num">' + fmt(r.like) + '</td>' +
'<td class="num">' + fmt(r.zaikan) + '</td>' +
'<td class="num">' + fmt(r.comment) + '</td></tr>';
}).join('');
document.getElementById('f-count').textContent =
'显示 ' + rows.length + ' / 共 ' + articleRows.length + ' 篇';
updateArrows();
}
// 点击合集单元格(事件委托)
var pop = document.getElementById('coll-pop');
var popMid = null;
function closePop() { pop.style.display = 'none'; popMid = null; }
function openCollPop(cell) {
popMid = cell.getAttribute('data-mid');
var cids = Object.keys(collections);
var html = cids.length
? cids.map(function (cid) {
var checked = collIdsOf(popMid).indexOf(cid) >= 0 ? 'checked' : '';
return '<label class="pitem"><input type="checkbox" data-cid="' + cid + '" ' +
checked + ' />' + esc(collections[cid].name) + '</label>';
}).join('')
: '<div class="pempty">还没有合集,先在下方创建。</div>';
html += '<div class="pnew"><input type="text" id="pop-new" placeholder="新建并归入" />' +
'<button id="pop-new-btn">添加</button></div>';
pop.innerHTML = html;
pop.style.display = 'block';
pop.querySelectorAll('input[type=checkbox]').forEach(function (cb) {
cb.addEventListener('change', function () {
toggleColl(cb.getAttribute('data-cid'), popMid);
renderTable();
});
});
var newInp = pop.querySelector('#pop-new');
function doCreate() {
var cid = createCollection(newInp.value);
if (cid) {
toggleColl(cid, popMid);
closePop();
refreshCollFilter();
renderTable();
}
}
pop.querySelector('#pop-new-btn').addEventListener('click', doCreate);
newInp.addEventListener('keydown', function (e) {
if (e.key === 'Enter') { e.preventDefault(); doCreate(); }
});
var pw = pop.offsetWidth, ph = pop.offsetHeight;
var rect = cell.getBoundingClientRect();
var left = Math.min(rect.left, window.innerWidth - pw - 10);
var top = rect.bottom + 6;
if (top + ph > window.innerHeight) top = Math.max(8, rect.top - ph - 6);
pop.style.left = Math.max(8, left) + 'px';
pop.style.top = top + 'px';
}
document.getElementById('tbody').addEventListener('click', function (e) {
var cell = e.target.closest('.coll-cell');
if (cell) openCollPop(cell);
});
document.addEventListener('click', function (e) {
if (pop.style.display === 'block' &&
!pop.contains(e.target) && !e.target.closest('.coll-cell')) closePop();
});
// 合集筛选下拉
function refreshCollFilter() {
var sel = document.getElementById('f-coll');
var cur = sel.value;
sel.innerHTML = '<option value="">全部合集</option>' +
'<option value="__none__">未归合集</option>' +
Object.keys(collections).map(function (cid) {
return '<option value="' + cid + '">' + esc(collections[cid].name) + '</option>';
}).join('');
sel.value = cur;
}
// ---------------- 合集管理模态框 ----------------
var overlay = document.getElementById('coll-overlay');
function renderModalList() {
var list = document.getElementById('m-list');
var cids = Object.keys(collections);
if (!cids.length) { list.innerHTML = '<div class="mnote">暂无合集,在上方创建。</div>'; return; }
list.innerHTML = cids.map(function (cid) {
return '<div class="crow" data-cid="' + cid + '">' +
'<span class="cname">' + esc(collections[cid].name) + '</span>' +
'<span class="ccnt">' + (collections[cid].article_ids || []).length + ' 篇</span>' +
'<button class="rename">重命名</button>' +
'<button class="del">删除</button></div>';
}).join('');
list.querySelectorAll('.crow').forEach(function (row) {
var cid = row.getAttribute('data-cid');
row.querySelector('.rename').addEventListener('click', function () {
var nameEl = row.querySelector('.cname');
var inp = document.createElement('input');
inp.type = 'text'; inp.value = nameEl.textContent; inp.className = 'cname';
nameEl.replaceWith(inp); inp.focus();
function save() {
var v = (inp.value || '').trim();
if (v) { collections[cid].name = v; saveCollections(); }
renderModalList(); refreshCollFilter(); renderTable();
}
inp.addEventListener('blur', save);
inp.addEventListener('keydown', function (e) {
if (e.key === 'Enter') { e.preventDefault(); save(); }
});
});
row.querySelector('.del').addEventListener('click', function () {
if (confirm('确定删除合集「' + collections[cid].name + '」吗?(不会删除文章)')) {
delete collections[cid]; saveCollections();
renderModalList(); refreshCollFilter(); renderTable();
}
});
});
}
function openModal() { renderModalList(); overlay.classList.add('show'); }
function closeModal() { overlay.classList.remove('show'); }
document.getElementById('btn-manage-coll').addEventListener('click', openModal);
document.getElementById('m-close').addEventListener('click', closeModal);
overlay.addEventListener('click', function (e) { if (e.target === overlay) closeModal(); });
function createFromModal() {
var inp = document.getElementById('m-new-name');
if (createCollection(inp.value)) {
inp.value = ''; refreshCollFilter(); renderModalList();
}
}
document.getElementById('m-create-btn').addEventListener('click', createFromModal);
document.getElementById('m-new-name').addEventListener('keydown', function (e) {
if (e.key === 'Enter') { e.preventDefault(); createFromModal(); }
});
// 合集备份 / 导入
document.getElementById('m-export').addEventListener('click', function () {
var blob = new Blob([JSON.stringify(collections, null, 2)], { type: 'application/json' });
var a = document.createElement('a');
a.href = URL.createObjectURL(blob);
a.download = '公众号看板合集备份_' + new Date().toISOString().slice(0, 10) + '.json';
a.click();
setTimeout(function () { URL.revokeObjectURL(a.href); }, 1000);
});
document.getElementById('m-import').addEventListener('click', function () {
document.getElementById('m-import-file').click();
});
document.getElementById('m-import-file').addEventListener('change', function (e) {
var f = e.target.files[0];
if (!f) return;
var fr = new FileReader();
fr.onload = function () {
try {
var obj = JSON.parse(fr.result);
if (obj && typeof obj === 'object') {
collections = obj;
saveCollections();
refreshCollFilter(); renderModalList(); renderTable();
} else { alert('文件格式不正确。'); }
} catch (err) { alert('文件格式不正确。'); }
};
fr.readAsText(f);
e.target.value = '';
});
// ---------------- 工具栏事件 ----------------
document.getElementById('f-start').addEventListener('change', function (e) {
state.start = e.target.value; renderTable();
});
document.getElementById('f-end').addEventListener('change', function (e) {
state.end = e.target.value; renderTable();
});
document.getElementById('f-coll').addEventListener('change', function (e) {
state.coll = e.target.value; renderTable();
});
document.getElementById('f-q').addEventListener('input', function (e) {
state.q = e.target.value; renderTable();
});
document.getElementById('f-reset').addEventListener('click', function () {
state.start = ''; state.end = ''; state.coll = ''; state.q = '';
document.getElementById('f-start').value = '';
document.getElementById('f-end').value = '';
document.getElementById('f-coll').value = '';
document.getElementById('f-q').value = '';
renderTable();
});
document.querySelectorAll('#head-row th.sortable').forEach(function (th) {
th.addEventListener('click', function () {
var k = th.getAttribute('data-key');
if (state.sortKey === k) state.sortDir = state.sortDir === 'asc' ? 'desc' : 'asc';
else { state.sortKey = k; state.sortDir = 'desc'; }
renderTable();
});
});
document.getElementById('btn-xls-30').addEventListener('click', function () { downloadExcel('30'); });
document.getElementById('btn-xls-all').addEventListener('click', function () { downloadExcel('all'); });
// ---------------- 初始化 ----------------
refreshCollFilter();
renderTable();
window.addEventListener('resize', function () {
charts.forEach(function (c) { c.resize(); });
});
})();
</script>
</body>
</html>
文件 5:README.md(部署说明,可选)
这个文件是给你自己看的说明书,建不建都不影响运行(注意:下面外层用了四道反引号,因为 README 正文里本身含代码块):
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
# 微信公众号数据看板(本地版 · 方案A)

纯本地运行,**不需要数据库、不需要云服务器、不花钱**。
一个 Python 脚本负责定时采集,结果存成 JSON 文件;一个 HTML 页面负责显示。
适用于 **统信 UOS(Debian 系 Linux)**,仅用 Python 标准库,无需 pip 安装。

> 本版已切换到微信「**发表内容新接口**」。老的群发数据接口(getarticlesummary 等)已下线(错误码 47009)。
> 新口径(**2025-11-01 起**)只统计「**阅读人数**」,**不再提供「阅读次数 PV」**;分享同样只保留「分享人数」。

---

## 一、你需要准备的信息

| 信息 | 在哪里获取 | 说明 |
|---|---|---|
| **AppID** | 微信公众平台 → 设置与开发 → 基本配置 → 开发者ID | 以 `wx` 开头 |
| **AppSecret** | 同上 → 开发者密码(点「重置」可见,需管理员扫码) | 只填到本机,**不要发给任何人、不要贴在聊天里** |
| **本机出口公网 IP** | 第一次运行脚本时会自动提示,或浏览器打开 `https://ip.cn` 查看 | 要加进白名单 |
| 公众号状态 | —— | 必须是 **已认证的订阅号 / 服务号**,未认证或个人号调不了数据接口 |

> 建议把整个 `wechat-dashboard` 文件夹放在固定位置,例如 `~/wechat-dashboard`,以后不要移动。

---

## 二、安装与配置(统信 UOS)

### 1. 确认 Python3

UOS 一般自带。在文件夹空白处 **右键 → 在终端打开**,执行:

```bash
python3 --version
```

能看到 `Python 3.7` 及以上即可(本版已在 Python 3.7 上验证)。若提示没有:

```bash
sudo apt update
sudo apt install python3
```

### 2. 填写 AppID / AppSecret

用文本编辑器打开 `config.json`,改成你自己的:

```json
{
  "appid": "wx你的真实AppID",
  "secret": "你的真实AppSecret",
  "lookback_days": 7,
  "article_detail_days": 30
}
```

- `lookback_days`:按「统计日」每日接口往回补几天,日常保持 `7`。
- `article_detail_days`:按「发表日」取多少天内发表的文章(含标题/链接、累计轨迹),默认 `30`。

### 3. 配置 IP 白名单(关键)

登录 [微信公众平台](https://mp.weixin.qq.com) → **设置与开发 → 基本配置 → IP 白名单**,
把本机出口公网 IP 加进去:

- 支持单个 IP:`1.2.3.4`
- 支持 IP 段:`1.2.3.4/24`(**不支持** `1.2.3.*` 写法)
- 家庭宽带 IP 偶尔会变,变了脚本会再次报错并提示新 IP,照提示更新即可。

---

## 三、首次运行

在文件夹里打开终端,执行:

```bash
chmod +x run.sh
./run.sh --days 30
```

- 首次建议 `--days 30`,拉取近 30 天的新格式数据(阅读、分享、来源、点赞、在看、留言、收藏)。
- 看到「采集完成」即成功。若报 IP 白名单错误,按屏幕提示把 IP 加好后再跑一次。

完成后,**双击 `index.html`**(或右键 → 用浏览器打开)就能看到看板。

---

## 四、设置每天自动同步(crontab)

### 1. 确认定时服务已开启

```bash
sudo systemctl enable --now cron
```

### 2. 编辑定时任务

```bash
crontab -e
```

在末尾加一行(把路径改成你的实际路径,可用 `pwd` 查看):

```cron
30 8 * * * cd /home/你的用户名/wechat-dashboard && python3 sync.py >> sync.log 2>&1
```

含义:**每天早上 8:30** 自动采集前一天数据(微信要求 8 点后数据才统计完)。
保存后每天到点自动更新,之后刷新 `index.html` 即可。

> 定时任务要求电脑在 8:30 处于开机联网状态。
> 当天没开机也不用担心,下次运行会自动补最近约 7 天。

---

## 五、看板功能(文章明细)

打开 `index.html`,在「文章明细」卡片顶部可以:

- **日期筛选**:选择开始/结束日期,只显示该范围内发表的文章;
- **合集筛选**:按合集过滤,或只看“未归合集”;
- **搜索**:按标题关键词搜索;
- **排序**:点击表头(标题、发表日期、阅读、分享、收藏、点赞、在看、留言)切换升序/降序,默认按发表日期倒序;
- **导出 Excel**:
  - `下载近30天Excel`:导出近 30 天发表的文章;
  - `下载全部Excel`:导出全部文章;
  - 表格列:发表日期、标题、合集、阅读/分享/收藏/点赞/在看/留言人数、链接。

### 关于“合集”

微信**没有开放“合集”接口**(后台的合集无法自动读取),所以这里的合集是**本看板的本地分组**:

1. 点 `管理合集` 创建合集(可重命名、删除);
2. 在明细表“合集”列点击某行,勾选合集即可归类,一篇文章可归入多个合集;
3. 合集保存在**当前浏览器**(localStorage),可在“管理合集”里 **备份/导入 JSON**,换浏览器或清理浏览器数据前建议先备份;
4. 合集会随 Excel 一起导出。

---

## 六、文件说明

| 文件 | 作用 |
|---|---|
| `sync.py` | 采集脚本(核心,不用手动改) |
| `config.json` | 配置:AppID / AppSecret / 回溯天数 |
| `run.sh` | 一键运行入口 |
| `index.html` | 数据看板页面,双击打开 |
| `token.json` | 自动生成,缓存 access_token(2 小时有效) |
| `store.json` | 自动生成,累积的全部历史数据(即"数据库") |
| `data.js` | 自动生成,看板读取的数据 |
| `sync.log` | 定时任务运行日志 |

> 备份时只需保留 `config.json`、`store.json`;其余文件都能重新生成。

---

## 七、常见问题

**Q:双击 index.html 看板是空的?**
A:还没采集数据。先运行 `./run.sh`,完成后刷新页面。

**Q:报错 `47009 / this api is offline`?**
A:老接口已下线。请使用本版脚本(已切换到新接口),不要改回旧接口名。

**Q:报错 `40164 / not in whitelist`?**
A:IP 白名单问题。脚本会显示本机当前 IP,把它加进公众平台白名单,等 1–2 分钟生效后重跑。

**Q:报错 `40001`?**
A:AppSecret 填错或 token 失效。核对 `config.json`,脚本会自动重取 token。

**Q:为什么没有阅读次数(PV)?**
A:为统一口径,微信自 2025-11-01 起下线了「阅读次数」,只保留「阅读人数」。2025-11-01 之前的历史次数可在公众平台后台「数据统计 → 历史数据入口」查看。

**Q:为什么没有更早的历史数据?**
A:微信不提供批量导出历史,新接口数据从 2025-11-01 起。从现在起每天采集,数据会越攒越多。

**Q:换网络 / 重启后不能用了?**
A:多半是公网 IP 变了。运行一次脚本,按提示把新 IP 加进白名单即可。
七、从零开始:手把手搭建与运行
第 1 步:新建文件夹并创建文件
按第六节的说明,在 wechat-dashboard 文件夹里建好 5 个文件,确认 config.json 已填好真实的 AppID / AppSecret。
第 2 步:在微信后台配好 IP 白名单
确认「基本配置 → IP 白名单」里已经加入了你的公网 IP(https://ip.cn 查到的)。
第 3 步:首次运行
Linux / 统信 UOS / macOS:
- 在
wechat-dashboard文件夹空白处右键 → 在终端打开; - 第一次运行先给
run.sh加可执行权限(只需一次):
1
chmod +x run.sh
- 开始采集,首次建议回溯 30 天:
1
./run.sh --days 30
Windows:
- 在
wechat-dashboard文件夹地址栏输入cmd回车(即可在当前目录打开命令行); - 执行:
1
python sync.py
第 4 步:观察运行结果
- 首次运行会先做一次「全量标题扫描」(约几分钟),它会把所有历史文章的标题补齐,期间不要中断;
- 看到类似下面的输出,就表示成功了:
1
2
采集完成:发表明细 xx 条、每日记录 xx 条。
已写入 store.json / data.js,用浏览器打开 index.html 即可。
- 如果报 IP 白名单错误:屏幕会直接显示你的公网 IP,把它加进后台白名单,等 1–2 分钟生效后再跑一次。
第 5 步:打开看板
双击 index.html(或右键 → 用浏览器打开)。你应该能看到:
- 顶部 5 个 KPI:累计粉丝、最新日净增、近 7 天阅读人数、近 7 天分享人数、文章总数;
- 阅读 / 分享趋势图、粉丝增长图、阅读来源构成图、文章阅读榜 Top 10;
- 文章明细表。
看板页面需要联网(图表库 ECharts 和 Excel 库通过 CDN 加载);数据本身则完全来自本机,不会上传。
八、设置每天自动同步
手动跑一次只能更新一次,要做到”自动同步”,需要配置定时任务。
Linux / 统信 UOS(crontab)
- 先确认定时服务开启:
1
sudo systemctl enable --now cron
- 编辑定时任务:
1
crontab -e
- 在末尾加一行(路径用
pwd命令查看后替换成你自己的):
30 8 * * * cd /home/你的用户名/wechat-dashboard && python3 sync.py >> sync.log 2>&1
含义:每天早上 8:30 自动采集前一天数据(微信要求上午 8 点后数据才统计完)。
- 要求电脑在 8:30 处于开机联网状态;
- 当天没开机也没关系,下次运行会自动补最近约 7 天。
Windows(任务计划程序)
- 打开「任务计划程序」→「创建基本任务」;
- 触发器选「每天」,时间设为
08:30; - 操作选「启动程序」,程序填
python,参数填sync.py,起始于填你的文件夹路径(如D:\wechat-dashboard); - 保存即可。
macOS(launchd / crontab)
可用 crontab -e,配置同 Linux;也可以用「自动操作 / launchd」。
九、看板功能说明(含合集的限制)
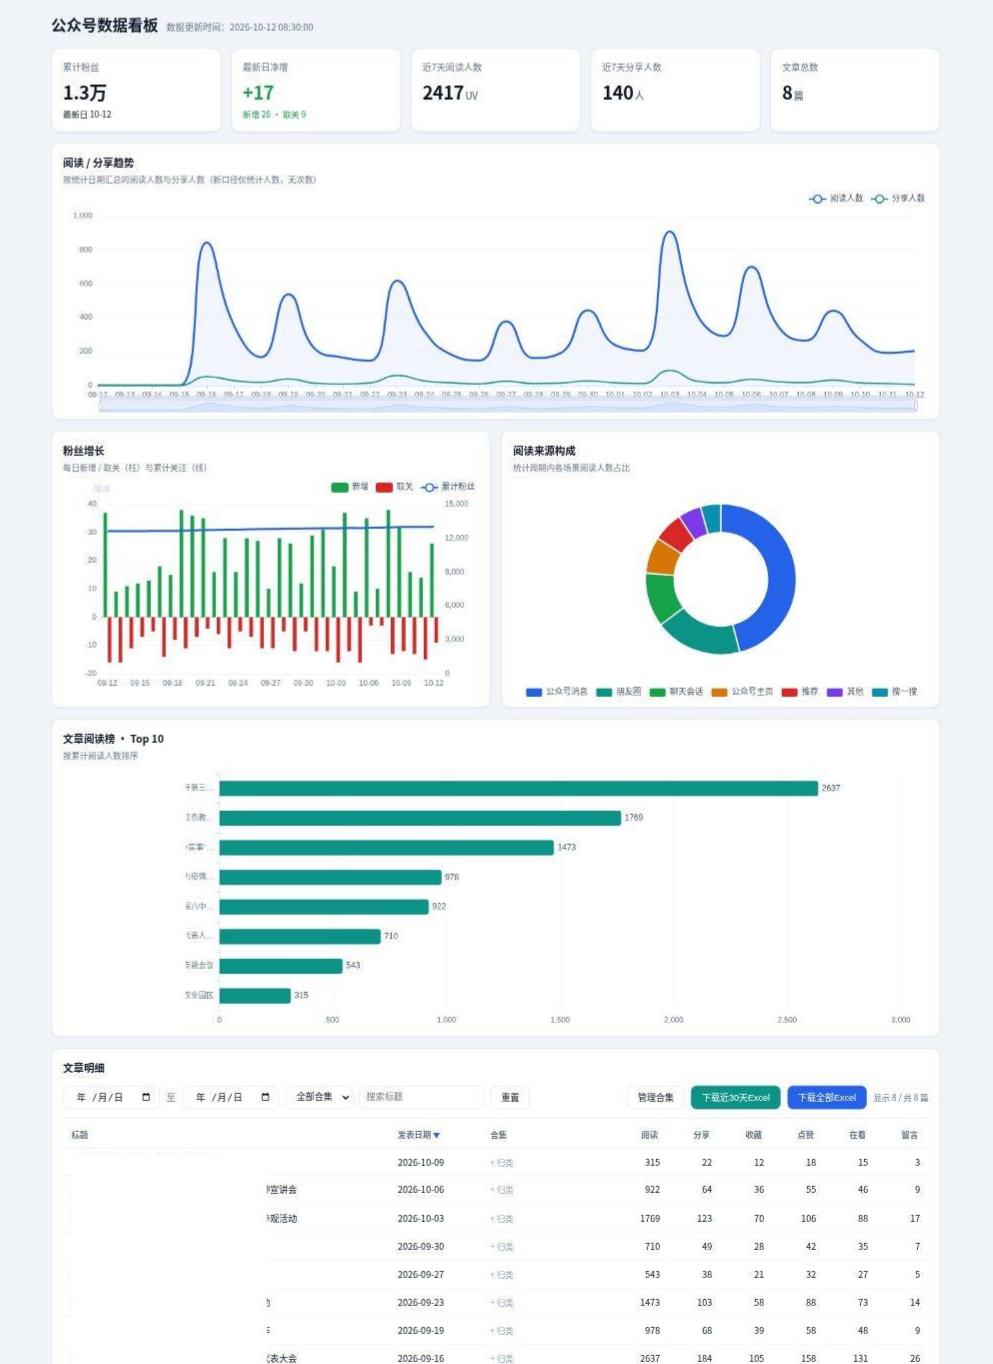
文章明细功能
打开 index.html,在「文章明细」卡片顶部可以:
- 日期筛选:选开始 / 结束日期,只显示该范围内发表的文章;
- 合集筛选:按合集过滤,或只看”未归合集”;
- 标题搜索:按关键词搜索;
- 排序:点表头(标题、发表日期、阅读、分享、收藏、点赞、在看、留言)切换升 / 降序,默认按发表日期倒序;
- 导出 Excel:
下载近30天Excel:导出近 30 天发表的文章;下载全部Excel:导出全部文章;- 列含:发表日期、标题、合集、阅读 / 分享 / 收藏 / 点赞 / 在看 / 留言人数、链接。
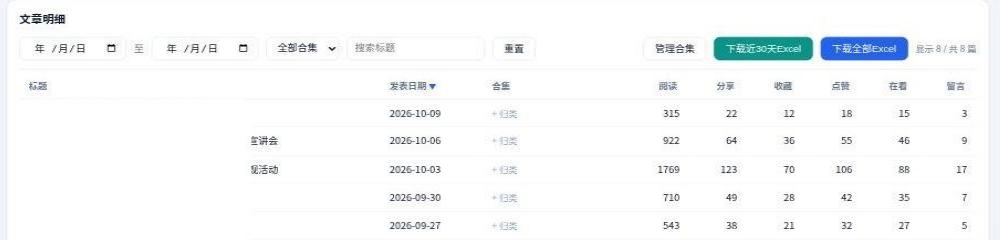
关于”合集”——务必了解这个限制
这是最容易被误解的一点:微信没有开放”合集”接口。
我核对过 getarticletotaldetail、freepublish/batchget、freepublish/getarticle 等所有相关接口,它们的返回字段里都没有”合集 / 话题”这一项。也就是说,用 access_token 走开放接口这条路,微信从设计上就没开放”每篇文章属于哪个合集”。真实的合集归属只存在于 mp.weixin.qq.com 网页后台(内容管理 → 合集)。
所以本看板的做法是:
- 点
管理合集创建合集(可重命名、删除); - 在明细表”合集”列点击某行,勾选合集即可归类,一篇文章可归入多个合集;
- 合集保存在当前浏览器(localStorage),可在”管理合集”里备份 / 导入 JSON,换浏览器或清理浏览器数据前建议先备份;
- 合集会随 Excel 一起导出。
如果你必须和微信后台的真实合集保持一致,目前只能在已登录的后台页面通过浏览器控制台读取页面数据、导出成 JSON 后再人工对照——这属于平台能力限制,不是脚本能解决的问题。
十、常见问题与错误码速查
常见错误码
| 错误码 | 含义 | 处理 |
|---|---|---|
40164 |
调用 IP 不在白名单 | 脚本会显示当前 IP,加进后台白名单,等 1–2 分钟重跑 |
40001 / 42001 |
access_token 失效 | 核对 AppSecret,脚本会自动重取 token |
47009 / 47011 |
接口已下线 | 用本文新版脚本,不要改回旧接口名 |
48001 |
接口未授权 | 确认公众号已认证、已具备数据接口权限 |
61503 |
数据尚未生成 | 当天 8 点后再查 |
61500 / 61501 |
日期格式 / 范围错误 | 检查日期格式,不要超过接口范围 |
40013 / 40125 |
AppID / AppSecret 错误 | 核对 config.json |
高频问题
Q:双击 index.html 看板是空的?
A:还没采集。先运行 ./run.sh(Windows 为 python sync.py),完成后刷新页面。
Q:为什么没有阅读次数(PV)? A:微信自 2025-11-01 起下线了「阅读次数」,只保留「阅读人数」。2025-11-01 之前的历史次数,可在后台「数据统计 → 历史数据入口」查看。
Q:为什么没有更早的历史数据? A:微信不提供批量导出历史,新接口数据从 2025-11-01 起。从现在起每天采集,数据会越攒越多。
Q:部分文章标题显示成”文章 2247508546_1”?
A:首次运行会做全量标题扫描补齐;如果仍有,可手动执行一次 python3 sync.py --full 强制重新扫描。
Q:换网络 / 重启后不能用了? A:多半是公网 IP 变了。运行一次脚本,按提示把新 IP 加进白名单即可。
十一、后续维护与备份
- 每天:定时任务到点自动采集,刷新页面即可看到最新数据;
- 漏跑:下次运行会自动补最近约 7 天;
- 备份:只需保留
config.json和store.json两个文件,其余都能重新生成; - 合集:合集存在浏览器里,定期在「管理合集」里备份 JSON;
- 换机迁移:把整个文件夹连同
config.json、store.json一起拷过去,在新机器上重新配好 IP 白名单即可。
写在最后
这套方案谈不上多高级,但它很”干净”:不依赖任何云服务器、不花钱、数据全部留在自己机器上,同时把”自动同步、趋势、榜单、明细、导出”这几件事都做到了。
过程中最值得记住的一条经验是:动手之前先把平台的边界搞清楚——哪些是接口能力问题,哪些是网络环境问题,把这两者分清楚,就不会在”为什么不行”上反复浪费时间。
如果你也在做类似的事,希望这篇文章能帮你少走几段弯路。